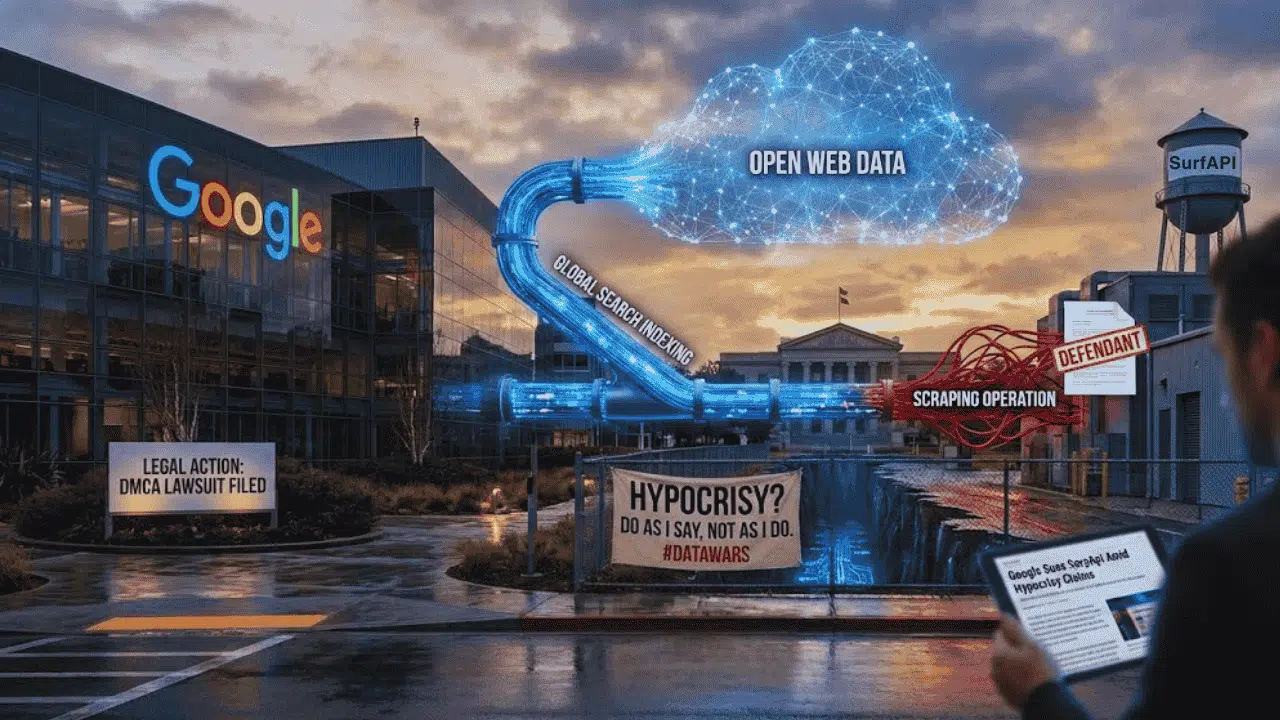
Google has filed a lawsuit against SurfAPI, a company known for collecting and reselling search engine data, accusing it of unlawfully scraping massive amounts of content from Google Search.
According to the complaint, SurfAPI allegedly sent hundreds of millions of automated and disguised search requests that mimicked real user behavior, allowing it to bypass Google’s security systems. Google argues that this was not simple web access but a deliberate attempt to evade safeguards designed to protect its infrastructure, licensed data, and business model.
Google claims that SurfAPI extracted search results at scale and repackaged them for commercial use, including content that Google itself licenses from third-party publishers and data providers. The company describes SurfAPI’s practices as unauthorized, harmful, and exploitative, stating that such activities undermine the value of Google Search and violate copyright laws. In the lawsuit, Google is seeking financial damages for each alleged violation and a court order to stop SurfAPI from continuing these practices.
From Google’s perspective, the case is about protecting its systems, its partners, and the integrity of its search products. The company maintains that while some level of web crawling is normal and expected on the internet, large-scale data scraping that circumvents protections and resells content crosses a clear legal and ethical line.
Understanding Crawling, Scraping, and Why This Case Matters
Web crawling and data scraping are often confused, but they serve different purposes. Crawling generally refers to automated systems scanning the web to discover and index webpages, a practice essential for search engines to function. Data scraping, on the other hand, involves extracting specific pieces of information—such as search results, prices, reviews, or article text—and reusing them elsewhere, often for profit.
In this case, Google argues that SurfAPI’s actions went far beyond acceptable crawling. The company alleges that SurfAPI deliberately masked its automated requests as human traffic, allowing it to collect data at a scale that ordinary users never could. Google also emphasizes that some of the scraped material includes content it pays to license, meaning SurfAPI may have profited from data it had no legal right to sell.
The lawsuit highlights a growing tension in the digital economy: data is the foundation of modern services, especially artificial intelligence, but the rules around who can collect, reuse, and monetize that data remain contested and unclear.
Hypocrisy Accusations and the “Do as I Say, Not as I Do” Debate
Google’s legal action has sparked criticism from parts of the tech industry, where some see the move as hypocritical. Critics point out that Google itself has faced lawsuits and public backlash over how it collects and uses data, particularly for training artificial intelligence systems like its Gemini AI. Artists, writers, publishers, and individual users have accused Google of using copyrighted content and personal data without sufficient consent.
This has fueled claims of “dual behavior” among major tech companies: aggressively gathering data to build AI products while blocking competitors from accessing their own platforms and datasets. Detractors argue that large companies want open access when it benefits them, but strict control when others attempt similar practices.
These criticisms are not limited to Google. Across the industry, companies promote strict enforcement of terms and copyrights while simultaneously pushing the boundaries of fair use and consent in AI training.
A Broader Pattern Across Big Tech and the AI Industry
The Google–SurfAPI dispute fits into a wider pattern involving many major technology firms. Social media platforms, e-commerce giants, and AI developers have all taken steps to restrict external scraping, monetize API access, or block automated tools. At the same time, several of these companies have been accused of using vast amounts of user-generated or copyrighted content to train their own AI systems.
For example, some tech leaders have publicly warned against “data plundering” by third parties, even as their companies rely heavily on user data to build proprietary AI models. Others have faced lawsuits from authors, publishers, and creators who claim their work was copied without permission for machine learning purposes.
As courts around the world continue to hear these cases, the outcomes will likely shape how data is collected, licensed, and protected in the age of artificial intelligence. The Google–SurfAPI lawsuit is not just about one company and one scraper—it reflects a much larger struggle over data ownership, fairness, and power in the modern tech ecosystem.