

Enterprise software vendors sell synthetic data as a legal backdoor around privacy regulations and data scarcity. The pitch promises that swapping real customer records for artificially generated rows lets you sidestep GDPR enforcement while feeding machine learning pipelines unlimited training content. This pitch ignores basic software engineering realities.
To answer what is synthetic data in practice: it is algorithmically constructed information engineered to mimic the statistical distribution of a source dataset. That is all it is. Treating artificial datasets as immune to privacy breaches or functionally identical to real-world ground truth introduces distinct failure points into production environments. When you replace raw human observations with generated proxies, you introduce risks like model collapse, neural memorization leaks, and silent performance degradation during market shifts.
Engineering teams need to evaluate the mathematical mechanics, privacy trade-offs, and operational boundaries of generated datasets before putting them into production pipelines.
Technical Generation Mechanisms
Real data reflects messy physical measurements, human actions, and financial transactions. Synthetic data, by contrast, relies entirely on probabilistic modeling or neural density estimation to calculate artificial rows.
Rule-Based Mocking
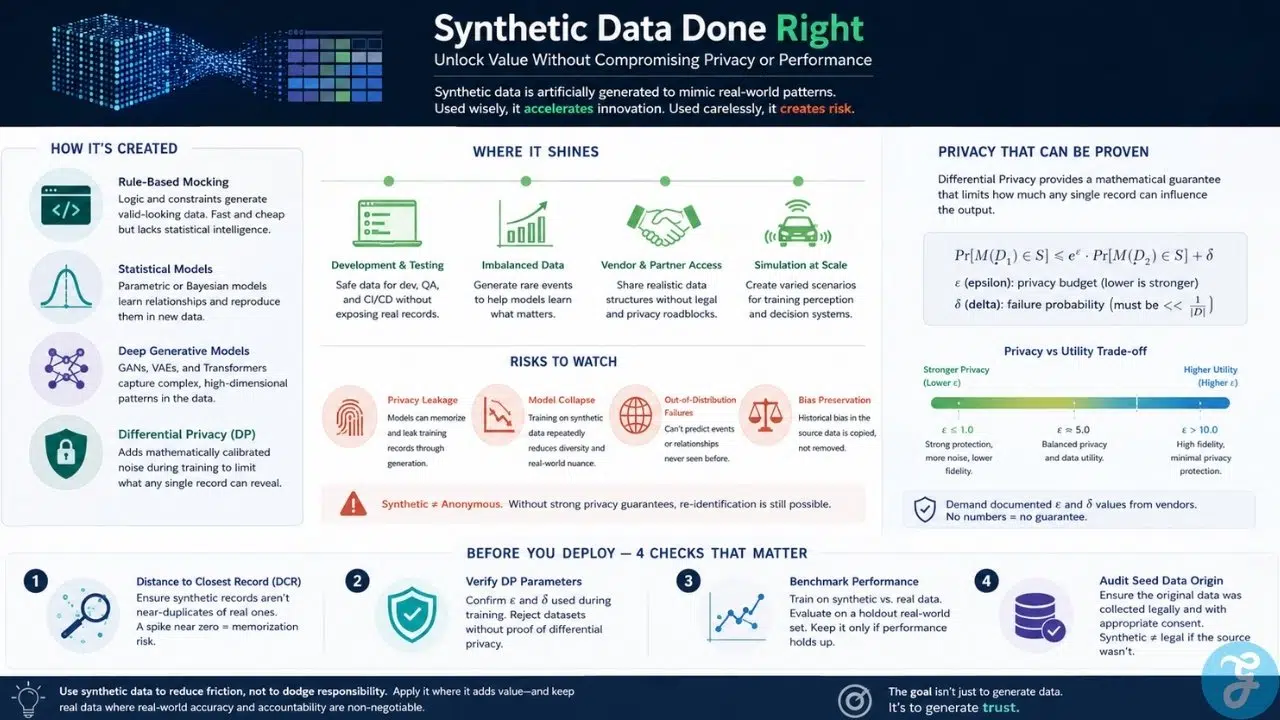
Programmers write explicit constraints, regular expressions, and logical field dependencies into a generation script. The script fills database tables with fake rows that pass basic structural validation. This costs almost nothing and works well for infrastructure load tests, but it contains zero statistical intelligence. Fields remain conditionally independent unless explicitly programmed otherwise.
Parametric and Bayesian Models
Statistical samplers map the joint probability distribution of a seed dataset. Parametric engines assume data fits standard mathematical distributions, while non-parametric engines like Bayesian networks map conditional relationships across variables without structural assumptions. If two columns correlate in the seed data, that relationship carries over to the generated output.
Deep Generative Architectures
Unstructured or high-dimensional datasets require deep neural networks to capture cross-variable dependencies:
Generative Adversarial Networks (GANs): A generator network transforms random noise into synthetic rows, while a discriminator network evaluates whether those rows came from the real seed data or the generator. They train simultaneously in a minimax game until the discriminator can no longer distinguish generated samples from real ones.
Variational Autoencoders (VAEs): An encoder network maps input records into a low-dimensional latent space parameterized by a mean and variance. A decoder network reconstructs full data rows by sampling vectors directly from that learned latent distribution.
Transformer Architectures: Adapted from large language models, engines like TabDDPM or CTGAN process structured rows as sequence tokens. The model predicts downstream field values based on prior attributes in the record, preserving long-range dependencies across wide database tables.
Neural Memorization and Differential Privacy
Assuming artificial data is private just because direct identifiers like names are removed is a major error. Generative models can easily memorize confidential records from the original dataset and leak them in the final output.
Deep neural networks often overfit when trained on small or complex datasets. Instead of learning broad trends, the network memorizes specific rare records verbatim. When generating new rows, the model outputs these memorized records with minor surface changes. If an artificial record matches a real person across dozens of fields, confidential data has been exposed.
Attackers do not need exact matches to compromise privacy. In a membership inference attack, an adversary analyzes the synthetic dataset to check if a target individual was used in the training data. Unusual combinations of information appearing in the output reveal that the person was present in the original source database. Because of this, generating synthetic data does not automatically satisfy statutory privacy laws like CCPA or GDPR.
Proving mathematical privacy requires implementing differential privacy during model training. This approach relies on two main concepts called epsilon and delta. Epsilon sets a strict limit on how much information a single record can leak. Delta represents the tiny probability of a total privacy failure, which must stay extremely small compared to the overall size of the dataset.
Differentially private training protects data using two key steps:
-
Gradient Clipping: Limits the maximum influence any single training record can have on the model parameters.
-
Noise Injection: Adds random mathematical noise to the training process to blur individual details before every update step.
Without strict limits where epsilon is set very low, claims about synthetic data privacy are unreliable. Setting a high epsilon value creates realistic synthetic rows but provides almost zero real protection against privacy attacks.
Practical High-Value Deployments
Synthetic datasets work best when used to bypass operational friction in low-stakes engineering environments.
Non-production staging and CI/CD: Software developers testing database schemas, user interfaces, or API contracts do not need real customer data. Shipping production database dumps to local developer laptops expands your security surface and violates least-privilege principles. Replacing production backups with schema-compliant artificial data lets developers test queries, validate migrations, and run build pipelines without exposing live customer PII.
Fixing extreme class imbalance: Fraud detection systems, network intrusion monitors, and medical diagnostic models usually deal with severe skew. Positive target events might account for less than 0.01% of total records. Standard classifiers trained on this data often default to predicting the majority class. Oversampling methods like SMOTE and specialized tabular GANs generate synthetic instances of rare events, providing enough signal for models to learn threat signatures.
Vendor proof-of-concept testing: Evaluating third-party software typically requires months of legal assessments and data processing agreements just to share sample data. Giving vendors a synthetic dataset matching your schema skips legal friction. Vendors can run performance benchmarks and integration tests on realistic structures while live records stay behind your firewall.
Simulating physical perception: Autonomous vehicles and robotics teams cannot rely solely on real-world driving logs to capture rare hazards. Creating virtual environments with ray-tracing, lighting shifts, and sensor noise lets perception models train against millions of edge cases safely.
Production Risks
Recursive Generation and Model Collapse
As generative content fills the web, organizations risk training new models on data produced by earlier artificial systems. This creates a recursive loop called model collapse. When a model trains on synthetic data generated by an earlier system, it loses information about the outer edges of the original distribution. Over several iterations, the model’s output narrows into repetitive, low-variance patterns that erase subtle real-world edge cases.
Out-of-Distribution Failures During Macro Shifts
Generative engines interpolate past patterns. They excel at copying correlations present in seed data, but they cannot extrapolate to sudden structural shifts. If a lender trains credit scoring models on synthetic data derived from five years of low inflation, that model will fail during an economic crash. The generator cannot output interactions that were missing from its training history.
Encoding Systemic Historical Bias
Seed data containing historical disparities will pass those exact disparities directly into generated outputs. Training downstream models on synthetic data does not clean or neutralize bias. It embeds that bias into a new dataset under the cover of artificial generation.
Verification Protocol
Run four technical checks before deploying synthetic datasets into production:
-
Calculate Distance to Closest Record (DCR). Compute the Euclidean or Gower distance between every synthetic record and its nearest neighbor in the seed dataset. If the distribution of DCR values spikes near zero, the generative model is memorizing training records and requires retraining with higher weight decay or gradient clipping.
-
Audit differential privacy parameters. Require internal teams or external vendors to document the exact epsilon and delta values used during training. Reject any dataset claiming privacy guarantees without explicit proof of mathematical noise injection during the training loop.
-
Benchmark downstream performance. Train two identical models: one on real data and one on synthetic data. Test both models against an untouched real-world validation set. Discard the synthetic dataset if the synthetic-trained model shows significant accuracy loss, calibration error, or higher error rates.
-
Audit seed data origin. Confirm the original dataset was collected with explicit consent for downstream processing. Transforming illegally collected PII into synthetic records does not eliminate the legal liability of the original collection.
Final Operational Assessment
Deploying synthetic data is an exercise in structural risk management. When engineering teams view generated rows as risk-free substitutes for actual production observations, they expose downstream models to silent failure modes. Technical maturity requires treating synthetic data as a specialized operational tool. Use it to insulate staging pipelines, stress-test database schemas, and correct severe dataset skew, but keep it out of core decision systems that demand empirical real-world validation.
Frequently Asked Questions (FAQs) About What Is Synthetic Data
What is synthetic data and how does it differ from anonymized data?
Synthetic data is artificially generated by algorithms to mimic statistical patterns, while anonymized data is real human data stripped of direct identifiers. Anonymized files carry higher re-identification risks because the underlying records remain intact, whereas synthetic data creates entirely new rows.
Is synthetic data compliant with GDPR and CCPA regulations?
Not automatically. If a generative engine memorizes source records, the artificial output can still leak confidential information. Full regulatory compliance requires mathematical differential privacy guarantees during training to prevent re-identification.
Can synthetic data replace real data entirely in machine learning?
No. Synthetic data only copies past correlations and cannot predict unprecedented real-world shifts. Over-relying on artificial datasets in core production pipelines leads to performance drops and model collapse.
How do engineering teams evaluate the quality of a synthetic dataset?
Teams test statistical accuracy, memorization risk, and downstream utility against real validation sets. A primary check involves calculating Distance to Closest Record to confirm the generator did not copy source rows verbatim.
What are the safest enterprise use cases for synthetic data?
The safest applications are populating non-production staging environments and running third-party vendor tests. It is also effective for balancing rare event classes in fraud detection without exposing live customer records.

























