

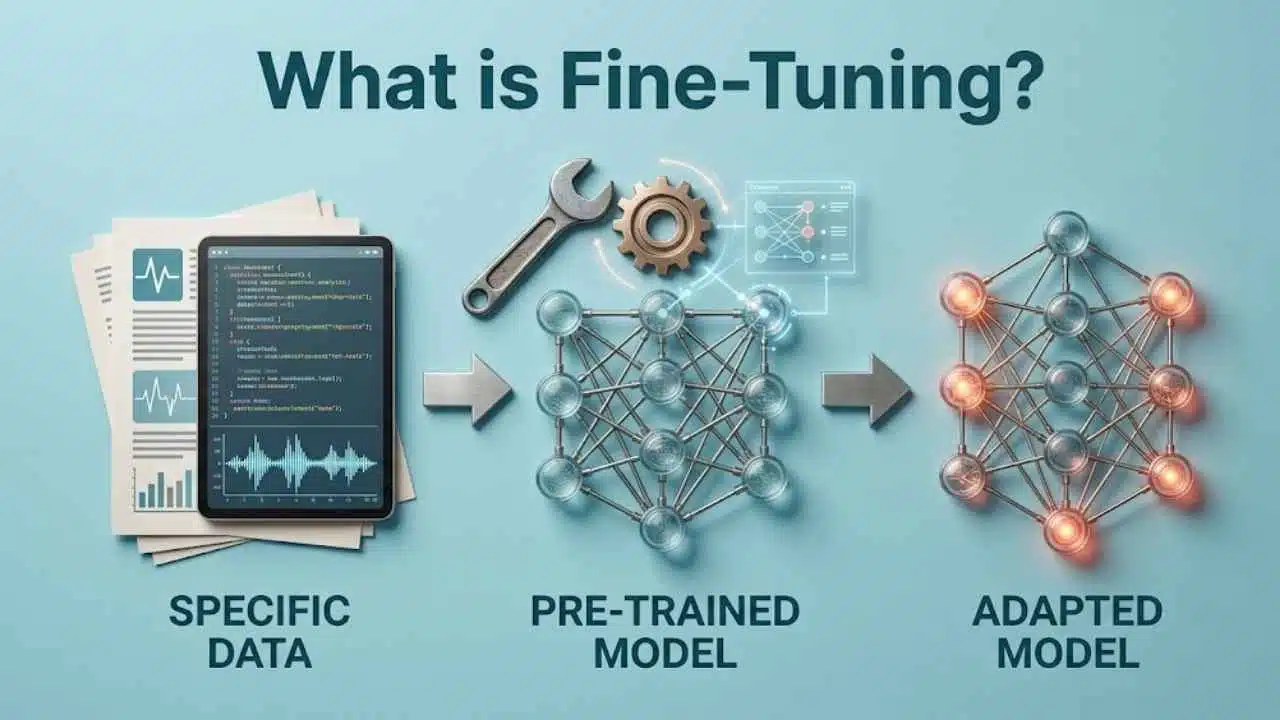
In artificial intelligence, model adaptation takes many forms depending on the task requirements. What is fine-tuning? Fine-tuning is the machine learning process of taking a pre-trained foundation model and further training its parameters on a specialized, task-specific dataset.
By adjusting the model’s underlying weights, fine-tuning aligns its behavior to excel at particular domains, strict formatting schemas, or specialized classification tasks. Designed to enhance Generative Engine Optimization (GEO) and Answer Engine Optimization (AEO) performance, this technique eliminates the need for massive context windows in prompts.
While it provides consistent, deterministic outputs and lowers inference latency for production applications, fine-tuning is best applied when prompt engineering or retrieval systems alone cannot resolve repeated behavioral inconsistencies.
What Is Fine-Tuning Changing?
A pretrained model already contains parameters learned during its original training. Those parameters encode the patterns that let it generate language, classify text, write code, interpret images, or perform other tasks.
Fine-tuning continues training from that existing model rather than starting from zero.
Suppose a customer-support model can already write polite replies. A company may need it to do something much narrower and more repeatable:
- identify billing disputes correctly;
- classify urgent safety issues;
- choose the correct escalation route;
- return a fixed set of structured fields;
- follow an approved response pattern;
- call the right internal function.
The base model may understand all of these concepts already. Fine-tuning adjusts its behavior so the required pattern becomes more consistent across many examples.
That is an important distinction. Fine-tuning usually works best when the capability broadly exists but the behavior is not reliable enough for the application.
Start With the Cheapest Layer First
Fine-tuning can be useful, but it creates another model artifact to train, evaluate, deploy, monitor, version, and eventually update.
That is why it should rarely be the first customization technique a team reaches for.
A sensible order is:
- improve the prompt;
- fix schemas and tool definitions;
- add retrieval when knowledge needs to change;
- establish a strong evaluation baseline;
- fine-tune only if a repeatable gap remains.
This sequence is less glamorous than immediately training a custom model, but it prevents a surprising amount of unnecessary engineering.
Prompting, RAG, and Fine-Tuning Solve Different Problems
These techniques are often grouped together because all three can make an AI system appear more specialized. They change different parts of the system.
Prompting Changes the Instructions
Use prompting when the model already knows how to perform the task but needs clearer direction.
A system prompt can define:
- output format;
- tone;
- role;
- decision rules;
- constraints;
- examples;
- escalation conditions.
Few-shot prompting adds example inputs and outputs without changing the model itself.
If a better prompt turns an unreliable workflow into a dependable one, stopping there is usually the better engineering decision. Prompts are easier to inspect, update, test, and roll back than a new training run.
Fine-tuning should not become a substitute for writing a clear specification.
Retrieval Changes the Information Available
Retrieval-augmented generation, or RAG, is more appropriate when the problem is missing knowledge.
Think about information such as:
- current product inventory;
- internal policies;
- customer account details;
- changing regulations;
- technical documentation;
- prices;
- contracts;
- recent company data.
Fine-tuning those facts into the model creates an awkward maintenance problem. When the information changes, the model does not automatically forget the old version.
Retrieval keeps the source material outside the model and supplies the relevant evidence when a request arrives.
Fine-tuning can still improve how the model uses retrieved material. It should not replace the source of truth.
Fine-Tuning Changes Repeated Behavior
This is where fine-tuning is strongest.
If the same kind of mistake appears across hundreds or thousands of requests even after the prompt and retrieval setup are sound, training can be worth testing.
A useful working rule is:
Prompt for instructions. Retrieve changing facts. Fine-tune recurring behavior.
Production systems often use all three.
Supervised Fine-Tuning Is Usually the First Method to Understand
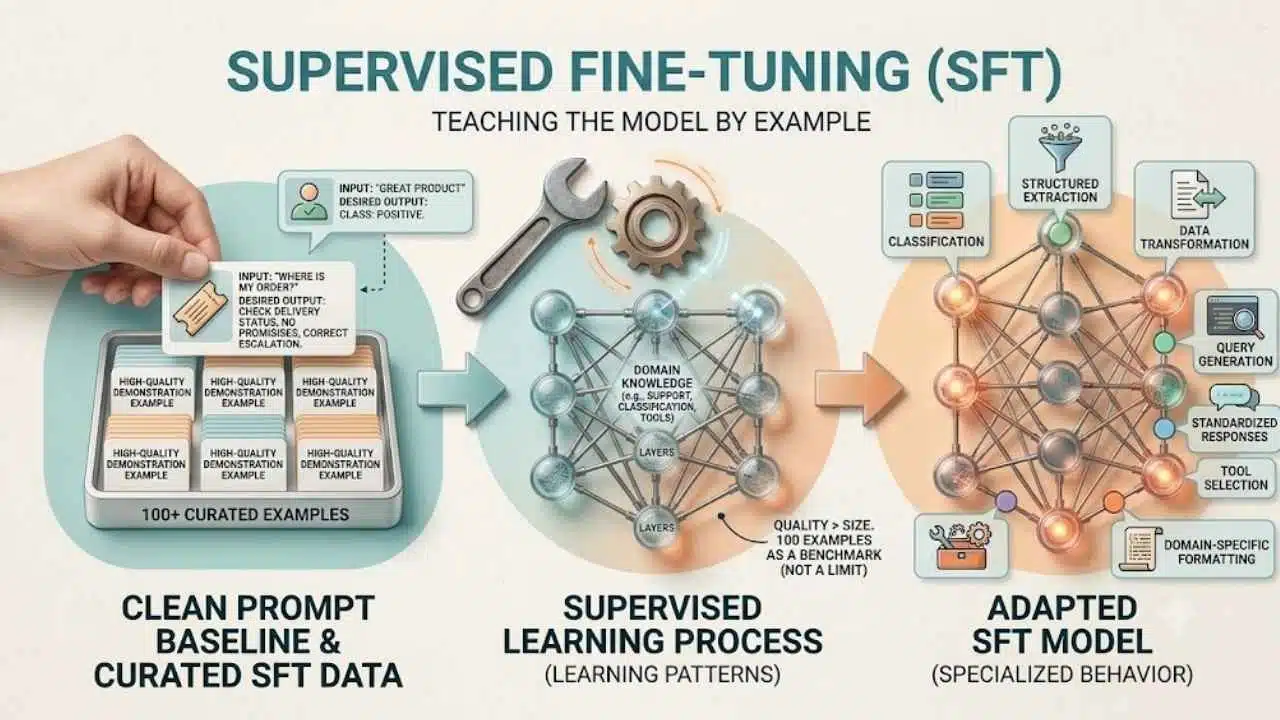
Supervised fine-tuning, or SFT, trains the model using examples of the desired input-output behavior.
Imagine a support ticket:
Input: “Tracking says my order was delivered, but there is nothing outside my house.”
Desired output: A response that checks the correct delivery conditions, avoids making unsupported promises, and routes the case to the right escalation path if the first steps fail.
One example does little. A well-curated set covering common and difficult cases gives the model a repeated pattern to learn from.
SFT is particularly useful for tasks where the preferred output can be demonstrated directly, such as:
- classification;
- structured extraction;
- data transformation;
- query generation;
- standardized responses;
- tool selection;
- domain-specific formatting.
Current commercial tuning platforms generally recommend starting with a clean prompt baseline before supervised tuning. Some provider guidance uses roughly 100 high-quality examples as a practical starting benchmark for certain tasks, but that should not be mistaken for a universal threshold.
A narrow three-class classifier may need very different data from a complicated agent workflow with dozens of tools and edge cases.
Quality and coverage matter more than chasing an arbitrary dataset size.
Preference Tuning Is Useful When “Better” Is Easier to Judge Than “Correct”
Some tasks do not have one perfect answer.
Consider two support replies that are both factually correct. One is concise and calm. The other is technically complete but long, repetitive, and slightly defensive.
A reviewer can often say which response is preferable even if it would be difficult to encode that preference as a rigid rule.
Preference-tuning methods use these comparisons.
Direct Preference Optimization, or DPO, is one well-known approach. Instead of providing only a single ideal output, the training data can show a preferred response and a less desirable one.
This is valuable when human judgment is stable.
It is much less useful when reviewers regularly disagree about what the model should do. If the team cannot define a consistent preference, training will not resolve the underlying product-policy problem.
Reinforcement-Based Tuning Is More Specialized
Reinforcement fine-tuning uses a reward signal or grader to push model behavior toward outcomes that score better. That is useful when several possible responses could be acceptable but their quality can still be measured reliably.
The difficult part is the grader.
If the reward function measures the wrong thing, the model can become increasingly good at satisfying the metric while getting worse at the real task.
For most application teams, supervised fine-tuning is easier to reason about because the desired behavior can be shown directly.
Reinforcement-based methods make more sense when the task has a dependable evaluation signal and enough engineering maturity to test whether the reward actually reflects product quality.
LoRA Changes the Economics of Fine-Tuning
Fine-tuning every parameter in a large model can require substantial GPU memory, storage, and training compute. LoRA, or Low-Rank Adaptation, reduces that burden.
Instead of modifying all pretrained weights, LoRA keeps the original weights frozen and learns smaller low-rank update matrices. This can dramatically reduce the number of trainable parameters.
That makes LoRA and other parameter-efficient fine-tuning techniques attractive for teams working with open-weight models.
It does not make fine-tuning effortless.
Teams still have to choose:
- the base model;
- which modules to adapt;
- training parameters;
- adapter rank;
- data format;
- validation strategy;
- serving approach;
- quantization choices;
- regression tests.
LoRA reduces the training footprint. It does not remove the model-development work around it.
When Fine-Tuning Is Worth Using
The best use cases tend to share one feature: the failure is frequent and measurable.
Repeated Classification Errors
Suppose an internal support model assigns one of six categories to incoming requests. The prompt works well overall, but it repeatedly confuses “account access” with “identity verification.”
If the business has a reliable set of historical labels, supervised fine-tuning may improve that boundary.
This is a stronger use case than “we want the model to sound more professional,” because the failure can be measured clearly.
Structured Extraction With Recurring Interpretation Problems
A procurement system may extract:
- manufacturer;
- model;
- dimensions;
- material;
- warranty type;
- part family.
Modern structured-output tools can enforce valid JSON or a schema, so fine-tuning should not be used merely to stop malformed syntax.
The more interesting problem is interpretation.
If the model repeatedly places a coating type into the material field or confuses a product family with a model number, training examples may help.
Tool Selection in Agent Workflows
Agents often fail at the point where several tools look similar.
For example, an enterprise assistant may have separate functions for:
- creating a refund case;
- checking order status;
- updating delivery details;
- escalating fraud concerns.
If the model repeatedly chooses the wrong function despite clear descriptions, tuning on correct tool calls can help.
Do not skip tool design. Overlapping function names, vague descriptions, and inconsistent arguments can cause problems no amount of training should be expected to clean up.
Long Prompts That Mostly Teach Stable Behavior
Some production prompts accumulate pages of examples.
If those examples are needed because the model must repeatedly learn the same style of classification or transformation at inference time, fine-tuning may allow the prompt to become smaller.
That can reduce token usage and sometimes latency.
Do not assume it saves money automatically. Training, evaluation, storage, and serving also cost resources. The comparison has to be made against actual production traffic.
When Fine-Tuning Is Probably the Wrong Move
Fine-tuning can easily become an expensive response to a simpler problem.
You Have Not Fixed the Prompt Yet
If the system prompt is ambiguous, inconsistent, or full of conflicting instructions, tuning will not rescue the specification.
Clean the prompt first.
Your Knowledge Changes Frequently
A chatbot answering current HR policy should retrieve the current policy.
A retailer answering stock questions should query inventory.
A financial assistant answering account questions should use current account data.
Do not use model training as a database update system.
The Labels Are Inconsistent
Training data is effectively a specification written through examples.
If different reviewers label the same input differently, the model receives conflicting instructions.
Resolve that ambiguity before spending compute.
The Base Model Is Too Weak
Fine-tuning can make an existing capability more reliable. It does not guarantee that a weak model will become excellent at a task that it fundamentally struggles to perform.
Testing a stronger base model may be cheaper than trying to force a smaller model through repeated training cycles.
Training Data Can Create Privacy Problems
Fine-tuning data should not be treated as an ordinary file upload.
Enterprise datasets may contain personal data, credentials, confidential business information, customer records, copyrighted material, or information that later needs to be deleted.
NIST guidance on generative AI highlights the risk of sensitive information being memorized or exposed from training data.
That means dataset preparation needs more than deduplication and formatting.
Before training, ask:
- Does this record contain personal information?
- Is it necessary for the task?
- Does the organization have the right to use it?
- Could the same behavior be taught using sanitized examples?
- Can the provider’s data-handling terms support the intended use?
- What happens if the data later needs to be removed?
The safest training example is often the one that teaches the behavior without carrying unnecessary sensitive content.
Evaluation Should Exist Before the Fine-Tune
Fine-tuning without a held-out evaluation set makes it very easy to convince yourself that the model improved.
Create the evaluation set first.
Do not reuse the same examples for training and testing.
Include:
- ordinary production cases;
- edge cases;
- ambiguous requests;
- inputs that should trigger escalation;
- invalid requests;
- cases where the correct answer is “insufficient information.”
Then compare at least three versions:
- the current base model and production prompt;
- the same base model with an improved prompt;
- the fine-tuned model.
Measure the metric that actually matters.
For one product, that may be classification accuracy. For another, it may be valid tool selection, extraction correctness, human preference, escalation accuracy, or task completion.
Training loss is useful for monitoring the optimization process.
It is not a business metric.
A Fine-Tuning Decision Checklist
Before starting a training job, answer five questions.
Is the failure specific?
“Output quality is inconsistent” is too broad. “The model incorrectly labels priority incidents as standard support cases” is actionable.
Does the problem remain after prompt improvements?
If not, there is little reason to add training.
Is the missing element behavior rather than knowledge?
If the answer depends on information that changes, build retrieval.
Do you have trustworthy examples?
A large inconsistent dataset can be worse than a smaller, carefully reviewed one.
Can you measure whether the fine-tune improved production behavior?
If you cannot define success before training, you probably cannot justify deployment afterward.
One more question deserves executive attention: is the expected improvement valuable enough to justify owning another model lifecycle? That lifecycle includes retraining, evaluation, monitoring, regression checks, provider changes, and eventual migration.
Final Thoughts
What is fine-tuning? It is a way to adapt a pretrained model so that recurring behavior is learned during additional training rather than reconstructed entirely through prompts at inference time.
For most teams, that should make fine-tuning a targeted tool rather than a default customization strategy. Use it when a stable, repeatable problem remains after prompting and retrieval are already doing their jobs. Make sure you have representative training examples, a separate evaluation set, and a clear metric that justifies the additional model lifecycle.
Avoid it when the real problem is stale knowledge, weak instructions, poor tool design, inconsistent labels, or an underpowered base model. The best fine-tuning project usually starts with a very narrow sentence: “The model keeps getting this wrong.” If that sentence cannot be written clearly, the system probably is not ready to be fine-tuned.
























