

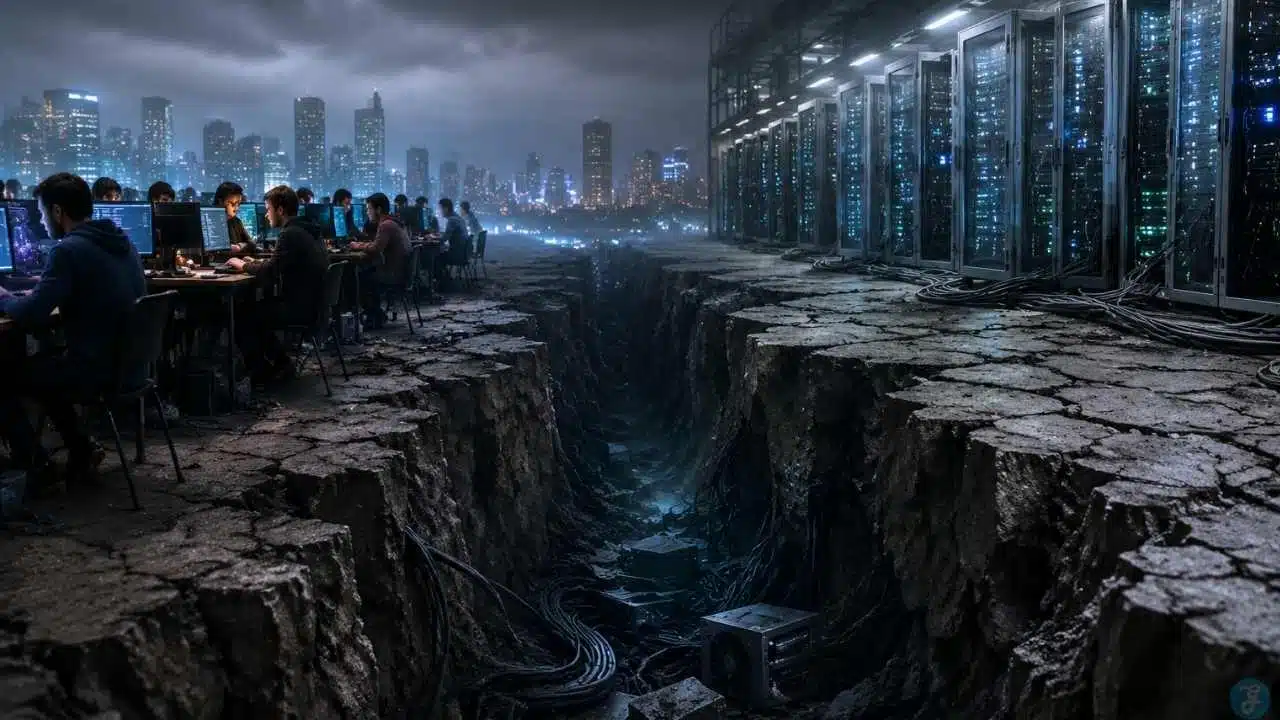
The rapid growth of AI has revealed a significant barrier: the compute gap open AI. Large companies can train massive models thanks to extensive GPU access, advanced infrastructure, and optimized cloud systems. Open-source teams, in contrast, often work with limited computing resources, smaller datasets, and slower iteration cycles. This disparity directly affects content generation, visual outputs, and the quality of text models.
In an era of original thought scarcity, this compute imbalance influences how unique and polished AI-generated outputs are. Open-source models may produce useful content, but without sufficient GPU access and training compute, outputs can feel inconsistent or generic. Teams attempting to scale these models must invest heavily in compute infrastructure or accept limitations in performance, speed, and output quality.
Understanding the compute gap is essential for creators, marketers, and developers who rely on AI models for content creation, automation, and creative workflows.
Historical Context of the Compute Gap
Early open-source AI projects relied on volunteer computing, small clusters, or limited cloud access. Large companies, such as Microsoft and Google, invested billions in GPU infrastructure, parallel training pipelines, and optimized data storage.
Open-source initiatives can innovate and experiment, but they face real-world limitations:
- Training models on large datasets requires thousands of GPU hours.
- Iterative optimization is slower due to limited compute.
- Reproducing enterprise-scale models is often impossible without major funding.
Example: The EleutherAI team demonstrated the feasibility of open-source large language models but could not match the training speed and size of proprietary corporate models.
Why GPU Access Is Critical
GPU access is critical because it directly determines how fast and efficiently AI models can be trained and run. High-performance GPUs allow teams to process massive datasets, handle complex computations, and generate outputs quickly. Without sufficient GPU access, open-source projects may struggle to train large models, limiting their performance and creativity.
For example, a text or image generation model might produce slower, less nuanced results when running on limited hardware. Teams relying on smaller setups must often compromise on model size or quality. Having robust GPU access ensures faster iteration, higher fidelity outputs, and more consistent results, making it a key factor in maintaining AI generated content originality.
GPU access is not optional—it determines the speed, scale, and complexity of AI models. High-performance GPUs allow:
- Training models with billions of parameters efficiently
- Faster experimentation with hyperparameters
- Higher-resolution outputs for visuals and video content
- Real-time model testing and deployment
Limited GPU access slows innovation, increases costs per experiment, and reduces model quality. For open-source projects, this creates a bottleneck where potential breakthroughs are delayed or unattainable.
The Role of Training Compute in Model Performance
Training compute refers to the total amount of processing power required to teach a model patterns, language, or visual representations. Models with insufficient compute often produce slower outputs, lower-quality content, and inconsistent results. Open-source projects frequently face trade-offs:
- They may need to reduce model size to fit available hardware, limiting sophistication.
- Training iterations take longer, slowing innovation and improvements.
- Complex, multi-modal models become impractical without large-scale compute.
Practical example: Teams working on open-source text generation may produce accurate but simplistic content compared to corporate models with billions of parameters, which can generate nuanced, context-aware outputs. For content creators, this directly affects AI generated content originality since smaller models may overfit or reuse patterns instead of creating unique responses.
Compute Access and its Impact on Content Quality
Limited compute access directly affects the quality, originality, and reliability of outputs. Models trained with insufficient GPU resources often produce content that is repetitive, less nuanced, or lower in fidelity. For text, this can mean simplified phrasing and predictable patterns. For visuals, images may appear generic or lack detail. Teams using open-source tools with restricted compute must spend extra time refining outputs, adding context, and testing for clarity.
For example, a small content team generating weekly blog posts or educational graphics may need manual editing to ensure each piece is engaging, distinct, and aligned with brand standards.
Limited compute access impacts not just speed but also the quality and originality of outputs. For example:
- Text Models: Fewer training iterations mean repetitive phrasing and simpler sentence structures.
- Visual Models: Lower-resolution training and smaller datasets produce generic imagery.
- Multi-Modal Content: Combining text, audio, and visuals becomes challenging without sufficient resources.
Marketers and content teams relying on smaller models must spend additional time refining outputs manually. Human oversight ensures that content is engaging, accurate, and distinctive, helping to maintain relevance in an era of original thought scarcity.
Practical Implications for Content Creation
Limited computing resources affect content creation in practical ways. Teams relying on smaller models must spend more time refining text, adjusting visuals, and testing outputs for quality. Open-source tools can be useful for experimentation, but without sufficient training compute or GPU access, content may feel repetitive or lack nuance.
For marketers producing social posts, blogs, or product descriptions, this means extra manual effort to maintain engagement and uniqueness. Human oversight—editing, context-setting, and creative adjustments—becomes essential. Understanding these limitations helps teams balance speed, quality, and originality in content workflows, ensuring outputs resonate with their audience.
For content creators, marketers, and educators, the compute gap presents real-world challenges:
- Tools backed by large tech companies produce faster, higher-quality content with fewer errors.
- Open-source solutions offer flexibility and experimentation, but outputs often require more human oversight.
- Maintaining AI generated content originality demands deliberate editing, context-setting, and iterative testing.
For instance, a team producing weekly blog posts may need to adjust tone, examples, and structure to ensure content feels unique. Understanding the compute gap helps teams balance efficiency, creativity, and originality across every project.
Risks of Relying on Low-Compute Models
Low-compute models pose several risks for content creators and teams relying on them. Without sufficient processing power, outputs can be slow, limiting the ability to scale campaigns or meet tight deadlines. Quality may suffer, with text or visuals appearing generic, repetitive, or lacking nuance. Complex tasks, like multi-layered storytelling or high-resolution image generation, often fail to reach professional standards. Teams must spend additional time manually refining outputs, which increases labor costs and reduces efficiency.
For example, marketers producing daily social posts may find that low-compute models produce repetitive phrasing or simplistic visuals, requiring extra human editing to maintain engagement and preserve originality.
- Slower output: Tasks that take hours on high-performance clusters may take days.
- Lower fidelity: Smaller models struggle with nuance in language and detail in visuals.
- Repetitive outputs: Limited compute can produce generic or predictable content.
- Higher labor costs: More manual refinement is needed to maintain quality.
While open-source tools remain valuable for experimentation, relying solely on them for high-volume production can compromise originality, engagement, and brand consistency.
Common Misconceptions
Many misconceptions surround the compute gap in open AI models. Some believe that open-source models are automatically more ethical or unbiased, but limited compute and smaller datasets can actually increase bias or reduce accuracy. Others assume that simply having access to code guarantees performance parity with enterprise systems—without sufficient GPU resources and training time, outputs are slower and often less reliable.
Some think transparency ensures better content quality, yet scale, iteration speed, and dataset breadth are equally critical. Realistically, creators need to understand that resources, infrastructure, and human oversight drive performance, not just access to open-source code.
- Open-source models are “enough” for professional-scale content—without compute, outputs often lag in quality.
- More computers doesn’t guarantee creativity—human guidance is still essential.
- Transparency in open-source models ensures better content—scale and iteration speed matter just as much.
Strategies to Overcome Compute Limitations
Teams facing limited compute resources can still produce high-quality outputs with the right strategies. Start by using smaller models for experimentation before scaling up. Combine outputs from multiple open-source models to cover gaps and add variety. Prioritize human review to refine content, correct errors, and maintain uniqueness.
Cloud services or shared GPU platforms can temporarily boost compute for training or large-scale tasks. Iterative testing ensures outputs improve over time without requiring constant high-end infrastructure. Planning workflows, batching tasks efficiently, and leveraging optimized datasets helps maximize limited compute while preserving original thought scarcity and content quality
- Use smaller models for prototyping, then refine content manually.
- Combine outputs from multiple open-source models to improve coverage and nuance.
- Integrate outputs into workflows supported by scalable cloud platforms for production.
- Track performance metrics, audience engagement, and originality to guide iterative improvement.
Brand Applications Across Industries
Brands across industries face unique challenges and opportunities when considering the compute gap in AI models. Large enterprises can leverage powerful platforms to produce high-volume content quickly and reliably, ensuring consistency across marketing campaigns, product visuals, and reports. Smaller businesses and startups may rely on open-source solutions, but they need to invest additional time in refining outputs to maintain quality and originality.
Educational platforms, for instance, must review generated materials to ensure accuracy and age-appropriateness. Even e-commerce brands benefit from automated content for speed but must guide outputs with human judgment to keep product descriptions and visuals compelling and distinctive.
- Marketing Agencies: High-volume campaigns benefit from enterprise-scale compute to ensure speed and quality.
- SMEs & Startups: Open-source models can be used for testing and experimentation, but outputs require human refinement.
- Educational Platforms: Content must be reviewed for clarity, accuracy, and appropriateness for different age groups.
- E-Commerce: Product descriptions, visuals, and social posts benefit from scalable compute to maintain high fidelity and originality.
Expert Tips to Preserve Originality
To preserve originality in content creation, human oversight is essential at every stage. Review outputs carefully for clarity, tone, and context, ensuring they match your brand’s voice. Customize visuals, language, and examples to avoid generic or repetitive results. Use smaller-scale models or experiments as drafts, then refine and layer insights manually.
Test outputs with real audiences to see what resonates, and iterate based on feedback. Incorporate unique perspectives, storytelling, and practical examples. Even with automated tools, deliberate editing, thoughtful prompts, and contextual awareness keep content distinctive, engaging, and aligned with the intended message.
- Always validate outputs for accuracy, tone, and relevance.
- Use human editing to add context, storytelling, and examples.
- Monitor trends in high-performance model updates to leverage new capabilities.
- Iteratively refine smaller models’ outputs to avoid repetitive phrasing.
- Incorporate narrative, examples, and audience-specific cues to differentiate content.
Final Thoughts
The compute gap open AI highlights a fundamental challenge in AI content production: access to large-scale processing power, GPUs, and optimized infrastructure determines output quality, speed, and originality. Large companies will continue to dominate due to scale, funding, and talent, while open-source models remain valuable for experimentation but require human oversight to maintain AI generated content originality. Content creators, marketers, and educators must understand these limitations to balance speed, creativity, and quality. Human insight remains the key differentiator that ensures outputs are distinctive, engaging, and truly original in a crowded digital landscape.
Frequently Asked Questions (FAQs) About the Compute Gap in AI
What is the compute gap in AI?
It’s the difference in computational resources between enterprise-scale platforms and smaller, open-source projects.
How does compute affect content quality?
Limited compute can reduce output fidelity, speed, and nuance, making content feel repetitive or generic.
Can open-source models compete?
They are excellent for experimentation but often require human oversight and refinement to match enterprise outputs.
How does this relate to originality?
Without sufficient compute and iteration, outputs risk being repetitive, impacting AI generated content originality.
Are open-source models still useful?
Yes, for testing, prototyping, niche applications, and learning, but scale is limited.
























